
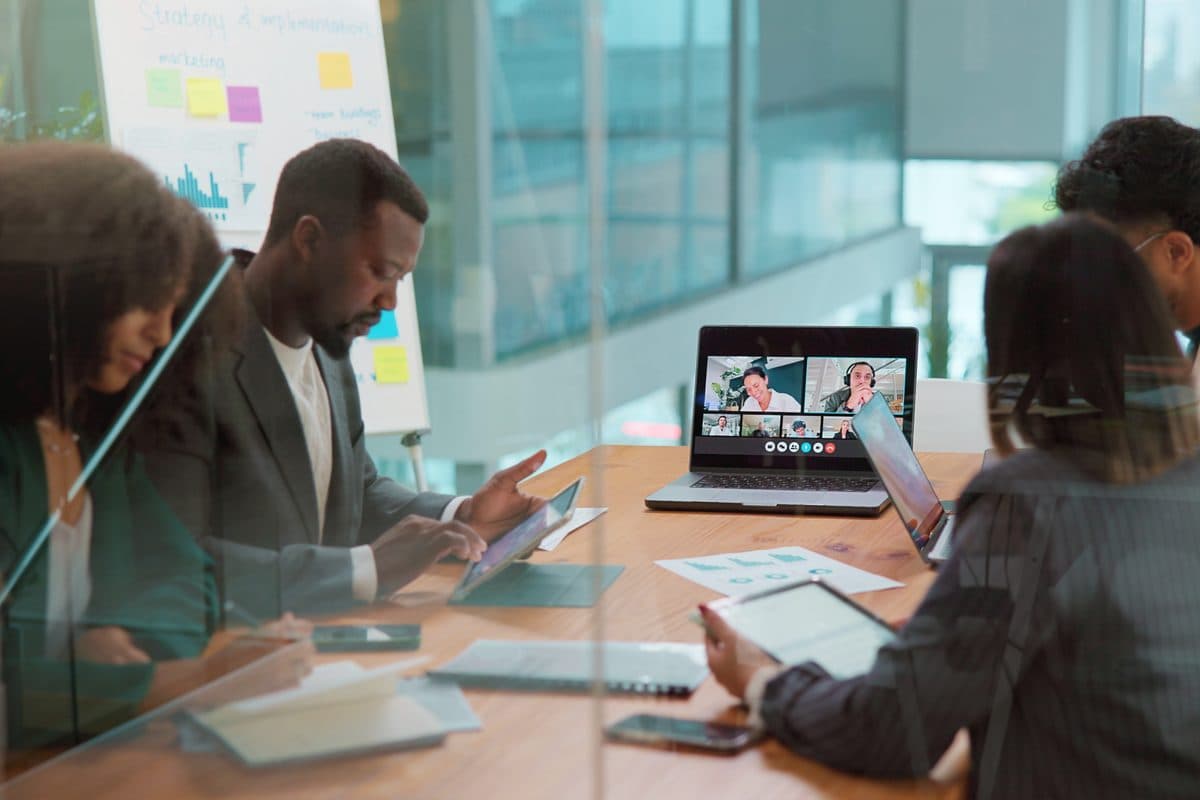
Orchestrated Systems: done without you.
Level 4 is multi-agent: specialized agents coordinate through shared state, handoffs and an orchestration layer, and run durably across hours or days.
Three companies, three targets. Each moves to the level its P&L needs.Three portfolio companies, three targets. What ships in one transfers to the next.
- Month-end close, Industrials: moves from Level 1 to Level 2. 14-day close, all by hand. 10-day close, numbers trusted.
- Insurance approvals, Healthcare: moves from Level 1 to Level 3. 45 min per patient, staff on the phone. 20 min, chatbot finds each insurer's rules. 4 min by agent, nurse signs off · est. $310K/yr.
- Renewal quoting, Software: moves from Level 1 to Level 4. 2 days per quote. Same day. 1 hour, agent drafts. Minutes · est. $480K/yr.
- Month-end close, Industrials portco: moves from Level 1 to Level 2. 14-day close at the portco. 10 days; the fund sees numbers a week sooner.
- Insurance approvals, Healthcare portco: moves from Level 1 to Level 3. 45 min per patient, staff on the phone. 20 min, chatbot finds each insurer's rules. 4 min by agent, nurse signs off · est. $310K/yr to EBITDA.
- Renewal quoting, Software portco: moves from Level 1 to Level 4. 2 days per quote. Same day. 1 hour, agent drafts. Minutes · est. $480K/yr · playbook to the next portco.
Three companies, three targets. Each moves to the level its P&L needs.Three portfolio companies, three targets. What ships in one transfers to the next.
- Month-end close, Industrials: moves from Level 1 to Level 2. 14-day close. 10-day close.
- Insurance approvals, Healthcare: moves from Level 1 to Level 3. 45 min each. 20 min each. 4 min · $310K/yr.
- Renewal quoting, Software: moves from Level 1 to Level 4. 2 days. Same day. 1 hour. Minutes · $480K.
- Month-end close, Industrials portco: moves from Level 1 to Level 2. 14-day close. 10-day close.
- Insurance approvals, Healthcare portco: moves from Level 1 to Level 3. 45 min each. 20 min each. 4 min · $310K/yr.
- Renewal quoting, Software portco: moves from Level 1 to Level 4. 2 days. Same day. 1 hour. Minutes · $480K.

 Azure
Several agents coordinate; people handle exceptions only.
Who does the workSoftware
A graph of agents, with shared state, evals, and a kill switch.
Technically: a graph of agents (LangGraph, CrewAI, AutoGen/AG2) or a managed platform (Bedrock AgentCore, Vertex Agent Builder, Mosaic Agent Bricks, Cortex Agents), with shared memory, evals as the heartbeat, observability, and edge-gated escalation.
Not human in the loop as default. HITL is the exception, not the rule: if the evals can't tell whether the output is right, fixing the evals is the priority, not stapling a reviewer to the loop.
L4 is also where lock-in becomes a real exit consideration. Bedrock, Vertex, Agentforce, and Mosaic Agent Bricks create durable platform dependencies. We build agents so the orchestration stays portable across these runtimes, so a buyer doesn't inherit a vendor.
Finance approves exceptions, not invoices.
Level 4: Orchestrated Systems
Several agents coordinate the close. One person signs off on exceptions. Nobody assembles anything.
Finance approves exceptions, not invoices. Add-ons and volume stop adding headcount.
What L4 looks like in the market
- Support. Agent-run tier 1 and tier 2; humans escalate only on edge cases.
- Sales. An SDR agent pool: research, outreach, reply classification, meeting booked. Pipeline scales without headcount.
- Finance. AP agent: invoice intake, matching, approval routing, exception escalation. Finance approves exceptions, not invoices.
- Engineering. Parallel autonomous SWE agents working the backlog the team can't hire against. Supervised by senior engineers; not autonomous in the L5 sense.
How L4 stalls
- Agents talking to agents, no observability. Failures uninterpretable, costs spike, trust dies.
- Multi-agent as theater. "Specialists" are the same model with different prompts, just more tokens.
- Skipping the evaluation suite. "We'll measure once it's live" means measuring via your first incident.
- HITL as default. Edge gating, not human in the loop. HITL as a default says we don't trust our evals. Fix the evals.
What Level 5 looks like
- The system initiates work unprompted: schedule, signal, or memory trigger.
- It learns from its own outputs (not just "we update the prompt monthly").
- Durable, governed memory across weeks and months.
- KPIs are business outcomes (revenue, retention, cycle time), not "tasks completed."
Moving from L3 to L4 runs $1.5M to $3.5M in total company investment over 12 to 18 months. We take a company here one workflow at a time, adding orchestration, durable execution and per-agent cost attribution once the workflow layer is proven.
The named picks at L4.


Scale is how we roll a proven workflow out across the portfolio. The governance is practice, not a product: we build on the runtime you already run (LangGraph, CrewAI, Bedrock, Vertex, Cortex, or Mosaic), keep the architecture cloud-portable, and ship every agent with audit, cost attribution, evals, and a deployment blueprint the next company reuses. "The architecture is the asset."
Framework vs. runtime: the distinction that orders the stack
Chosen for control & inspectability.
Chosen for governance & data proximity.
Keeping the framework decoupled from the runtime lets us change one without re-platforming the other. How we engage →
What L4 actually looks like in a portfolio company
| Function | In practice | Signal | What it saves |
|---|---|---|---|
| Support | Agent-run tier 1 and tier 2; humans escalate only on edge cases | Outcome-priced | |
| Sales | An SDR agent pool: research → send → reply classification → meeting booked | Fleet scale | |
| Finance | AP agent: invoice intake → matching → approval routing → exception escalation | Approve exceptions only | |
| HR | Recruiting agent: inbound screening → scheduling → first-round scorecard | Recruiter sees finalists | |
| Engineering | Multi-Devin or Claude Agent SDK fleet working a backlog you can't hire against | Parallel SWE agents |
What L4 looks like in the market.
Agent-run tier 1 + 2
Sierra (outcome-priced), Decagon (multi-agent enterprise), or LangGraph-built with BOD's governance practice around it. Human escalation only at policy edges.
SDR agent pool
A fleet of research → outreach → reply classification → meeting agents, with per-agent budgets and a shared evaluation suite. Pipeline scales without headcount.
AP agent fleet
Invoice intake → matching → approval routing → exception escalation. Finance approves exceptions, not invoices.
Recruiting fleet
Inbound screening → scheduling → first-round scorecard. The recruiter takes only shortlisted candidates into final rounds.
Multi-Devin or Agent SDK fleet
Parallel autonomous SWE agents working the backlog the team can't hire against. Supervised by senior engineers; not autonomous in the L5 sense.
The agent becomes the flagship value
Onboarding agent runs sign-up → first value. CS agent watches usage, flags risk, drafts save motions. Pricing model starts shifting seat-based → outcome-based.
How L4 stalls.
- Agents talking to agents, no observability. Failures uninterpretable, costs spike, trust dies.
- Multi-agent as theater. "Specialists" are the same model with different prompts, just more tokens.
- Bedrock Agents as a shortcut. Managed runtime doesn't replace evals, observability, or workflow ownership.
- No memory governance. Persistent memory inherits permissions from nothing; CFO query surfaces HR doc 90 days later.
- Skipping the evaluation suite. "We'll measure once it's live" means measuring via your first incident.
- HITL as default. "Edge gating, not human-in-the-loop. HITL as a default is a design decision that says we don't trust our evals. Fix the evals."
What L5 looks like.
- The system initiates work unprompted: schedule, signal, or memory trigger.
- It learns from its own outputs (not just "we update the prompt monthly").
- Durable, governed memory across weeks and months.
- It can refuse work, knows what's out-of-scope or needs escalation.
- KPIs are business outcomes (revenue, retention, cycle time), not "tasks completed."
Common questions.
What is Level 4 AI maturity?
Level 4 (L4) is multi-agent: specialized agents coordinate through shared state, handoffs and an orchestration layer, and run durably across hours or days. In plain terms, several agents coordinate and people handle exceptions only. The work is done by software.
How much does it cost to move from L3 to L4?
Moving from Level 3 (L3, where software runs a whole workflow and a person reviews the exceptions) to L4 runs $1.5M to $3.5M in total company investment over 12 to 18 months. We take a company here one workflow at a time, adding orchestration, durable execution and per-agent cost attribution once the workflow layer is proven.
What does Level 4 look like in a portfolio company?
At Level 4 (L4, where several agents coordinate across functions), finance approves exceptions, not invoices: an AP agent handles invoice intake, matching, approval routing and exception escalation. Support runs tier 1 and tier 2 with agents and humans escalate only on edge cases, and an SDR agent pool scales pipeline without headcount.
Do people still review the work at Level 4?
Only the exceptions. At Level 4 (L4, where several agents coordinate across functions), human in the loop is the exception, not the rule: people handle edge cases, gated at the edge, and the agents run the rest. If the evals can't tell whether the output is right, fixing the evals is the priority, not stapling a reviewer to the loop.
Does Level 4 lock a company into one AI vendor?
It can, which is why Level 4 (L4, where several agents coordinate across functions) is where lock-in becomes a real exit consideration: Bedrock, Vertex, Agentforce and Mosaic Agent Bricks create durable platform dependencies. We build agents so the orchestration stays portable across these runtimes, so a buyer doesn't inherit a vendor.
How does Stage 3, Scale, take Level 4 across a portfolio?
Scale is how we roll a proven workflow out across the portfolio. The governance is practice, not a product: we build on the runtime you already run, keep the architecture cloud-portable, and ship every agent with audit, cost attribution, evals and a deployment blueprint the next company reuses.