
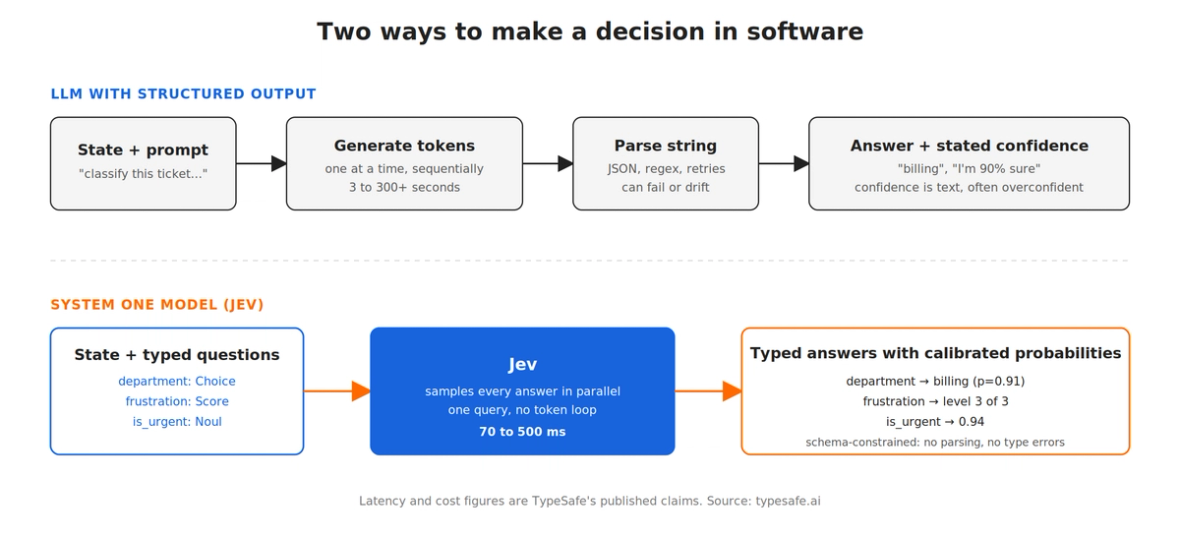
Most of the LLM calls inside a production agent aren't writing anything. They're deciding something. Which team gets this ticket. Is this tool call safe to run. Does this request need the expensive model or the cheap one. Each of those decisions costs a full generation pass, a few seconds of latency, and a parse step that fails more often than anyone likes to admit. TypeSafe AI's new model, Jev, is built for exactly that slice of the work, and it changes the economics enough to be worth understanding now.
what Jev is
Jev is the first model in a category TypeSafe calls System One models. It doesn't generate text. You send it a state (a support ticket, a log line, a chat transcript, a JSON blob) and a set of typed questions, and it returns typed answers with calibrated probabilities. No string comes back, so there's nothing to parse and nothing to validate.
The name borrows from Daniel Kahneman's split between fast, intuitive System 1 thinking and slow, deliberate System 2 thinking. Frontier LLMs with chain of thought are System 2 machines. Jev is meant to be the System 1 half: quick judgments on bounded questions.
TypeSafe was founded by Diogo Almeida, who worked on ChatGPT at OpenAI. The company announced Jev on September 15, 2026, and it's in early access behind a waitlist. LangChain shipped an integration package the same week, which is what got our attention.
Three things make it different from calling an LLM with structured outputs:
- It samples all answers in parallel in a single query instead of token by token, which is where the speed comes from.
- Outputs are constrained to the schema you define, so an invalid value or type error can't happen.
- It's trained with a method TypeSafe calls Reinforcement Learning for Calibrated Decisions (RLCD), which optimizes for probabilities that are honest about their own uncertainty rather than for human preference (RLHF) or verifiable correctness (RLVR).
the three question types
Everything you ask Jev is one of three shapes.
A Noul is a yes/no question. It returns the probability that the statement is true.
A Choice picks one option from a set you define (up to 255 of them) and returns a probability for each.
A Score rates the state against an ordered rubric and returns a position on that scale.
You can ask many questions about the same state in one request, and they run in parallel. Adding a fifth question to a request costs almost nothing extra in time or money, which turns out to matter a lot for how you design around it.
how to call it
Install the SDK and set your API key:
shpip install typesafe-sdk
export TYPESAFE_API_KEY=your_key_here
Then send a state and some questions. This example triages an inbound support message three ways at once:
pythonfrom typesafe_sdk import Choice, Noul, Score, TypeSafeClient

client = TypeSafeClient()

state = (
    "Third time writing in. The refund you promised on the 4th still "
    "hasn't landed and my card was charged again this morning. "
    "I need this fixed today."
)

response = client.system_one(
    state=state,
    questions={
        "department": Choice(
            instructions="Which team should handle this",
            criteria={
                "billing": "Payment, refund, or subscription issues",
                "technical": "Bugs or integration problems",
                "sales": "Pricing or account questions",
            },
        ),
        "frustration": Score(
            instructions="How frustrated the customer appears",
            criteria=[
                "Calm, just stating facts",
                "Frustrated but civil",
                "Very angry, strong language",
            ],
        ),
        "is_urgent": Noul(
            instructions="The message conveys urgency or time-sensitivity"
        ),
    },
)

print(response.answers["department"].choice)      # "billing"
print(response.answers["frustration"].score)      # position on the 3-level rubric
print(response.answers["is_urgent"].noul)         # probability, e.g. 0.94
The response also carries the full probability distribution for each answer, so you can set your own thresholds. A Noul at 0.94 goes straight to the urgent queue. A Noul at 0.55 might get a second look from a person. That's a different design surface than a model that just says "yes."
If you'd rather hit the API directly, it's one endpoint:
pythonimport requests

response = requests.post(
    "https://api.typesafe.ai/v1/systemone",
    headers={"Authorization": "Bearer YOUR_KEY"},
    json={
        "model": "jev-latest",
        "state": "Customer emailed twice this week about a failed refund...",
        "questions": {
            "category": {"type": "choice", "options": ["billing", "technical", "sales"]},
            "urgency": {"type": "score", "min": 0, "max": 100},
        },
    },
)
print(response.json())
where it fits in an agent harness
The most useful way to think about Jev is as a cheap decision node you can drop into the places where your agent loop currently makes a judgment call by spending a full LLM turn. LangChain's langchain-typesafe package ships two middleware examples that show the pattern.
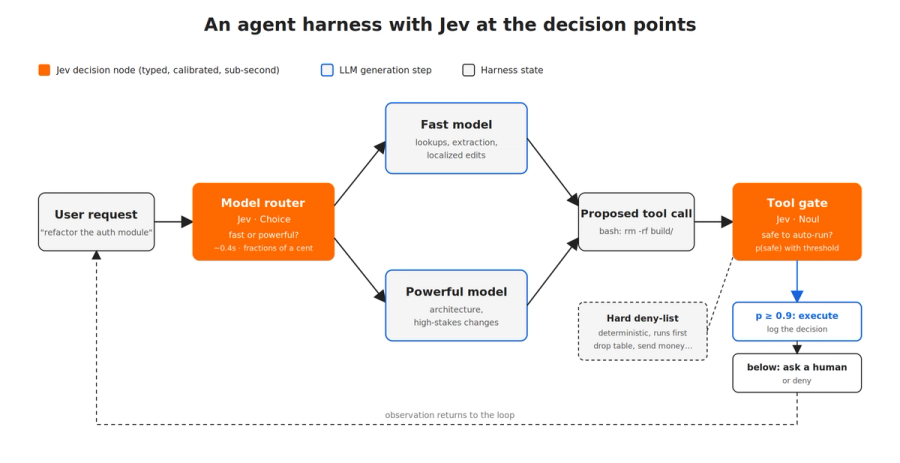
Model routing. Before the agent runs, Jev looks at the request and picks the cheapest model that can handle it. Direct lookups and small edits go to a fast model. Architecture questions and high-stakes changes go to the powerful one.
pythonfrom langchain.agents import create_agent
from langchain_typesafe.experimental.middleware import (
    ModelChoice,
    ModelRouterMiddleware,
)

router = ModelRouterMiddleware(
    choices={
        "fast": ModelChoice(
            model="openai:luna",
            criteria="Direct lookups, extraction, and localized changes.",
        ),
        "powerful": ModelChoice(
            model="openai:sol",
            criteria="Architecture and high-stakes decisions.",
        ),
    },
    instructions="Choose the least costly model that can complete the task.",
)

agent = create_agent("openai:gpt-5.6-luna", middleware=[router])
Tool gating. Before a tool call executes, Jev classifies whether it's safe to run without a human in the loop. This is the same idea the closed-source coding harnesses use for their "auto" modes, made available to anyone building their own.
pythonfrom langchain.agents import create_agent
from langchain_typesafe.experimental.middleware import AutoModeMiddleware

guardrail = AutoModeMiddleware(tools=["bash"])

agent = create_agent("openai:gpt-5.6-luna", middleware=[guardrail])
A note on the gate: Jev returns a probability, not a guarantee. For anything irreversible (dropping a table, sending money, deleting a bucket), keep a deterministic deny-list in front of it and let Jev handle the wide middle band of calls that are probably fine but deserve a check.
Beyond routing and gating, the pattern shows up anywhere you have high volume and a bounded answer set: intent classification, lead scoring, log triage, eval grading, content moderation, and confidence-gated handoffs to a person.
what the numbers look like
These figures come from TypeSafe's own evaluation suite, which the company built internally across four workflows (security, observability, invoicing, customer service). Treat them as a starting point, not independent verification. On classification tasks TypeSafe claims up to 200x faster inference and 400x lower cost than comparable LLMs.
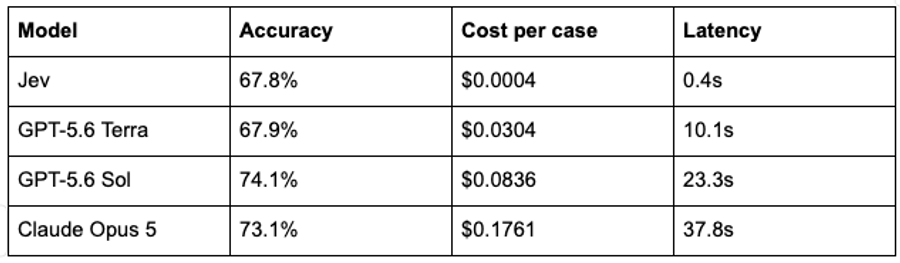
Read the whole table. Jev matches the mid-tier frontier model on accuracy at roughly 1/76th the cost and 25x the speed. It doesn't match the top-tier models, which hold a 5 to 6 point lead. That gap is the trade you're making.
Pricing is $0.042 per million input tokens with output unmetered. TypeSafe says it can't prove the price isn't subsidized during early access but expects it to fall over time.
The structured output claim is the one that holds up without caveats. Because answers are constrained to your schema, the type error rate is zero by construction. TypeSafe's comparison put frontier LLMs between 17% and 45% on the same structured output tests.
what it can't do
Jev only works on questions where you already know the finite set of valid answers. It can't write a reply, explain its reasoning, do arithmetic, or handle a multi-step task. If you need a rationale attached to a decision for an audit, you'll still need an LLM in the loop for that part.
Early users have also flagged that it can't abstain. A Noul always returns a probability, so "I don't know" has to be something you infer from the distribution rather than something the model tells you. Accuracy also degrades when the state is padded with irrelevant material, so the discipline of sending a tight, relevant state matters more here than it does with a long-context LLM.
And all of the demos and benchmarks so far come from TypeSafe. Independent evaluations will tell us how well the calibration holds up on messy production data. We'd want to see that before betting a compliance workflow on it.
why we think this matters
For the last two years the default answer to "how do we make a decision inside this pipeline" has been "call the LLM and parse the JSON." That works, and it's expensive and slow in ways that compound at volume. A portfolio company scoring 5 million support interactions a month is paying frontier-model prices for what is mostly classification.
Jev is the first credible attempt to give that work its own model class. Even if TypeSafe's numbers land at half their claimed advantage, the architecture argument stands: put fast, typed, calibrated decisions where decisions belong, and save generation for the places that need words.
If you're building agents right now, the practical move is to audit your loop for decision points that are currently full LLM turns. Route them, gate them, score them. Then measure what the frontier model is still doing and whether it needs to be.
We're already testing Jev against a few of our own routing and eval-grading workloads. If you want to talk through where it might fit in yours, talk to our engineering team.